n8n
n8n vs Make in 2026: Pricing, Limits and Trade-Offs
n8n vs Make in 2026: how execution billing beats per-module credits, where each platform wins, and the n8n 3.0 migration to plan for before you commit.
5 Nov 2026 · 10 min read · Abhijeet Singh
On this page 7 sections
Most comparisons of n8n vs Make open with node counts and interface screenshots. That is the wrong place to start. The decision that shapes your automation stack over the next two years is the billing meter, because the meter quietly dictates how you are allowed to build. Choose the wrong one and you will spend a year writing awkward workflows to dodge your own invoice.
This guide compares the two platforms on the things that actually move your bill and your architecture: how each one counts what you run, what self-hosting really buys you, how the AI agent layer is priced, and what n8n 3.0 changes.
n8n vs Make: the billing meter is the real difference
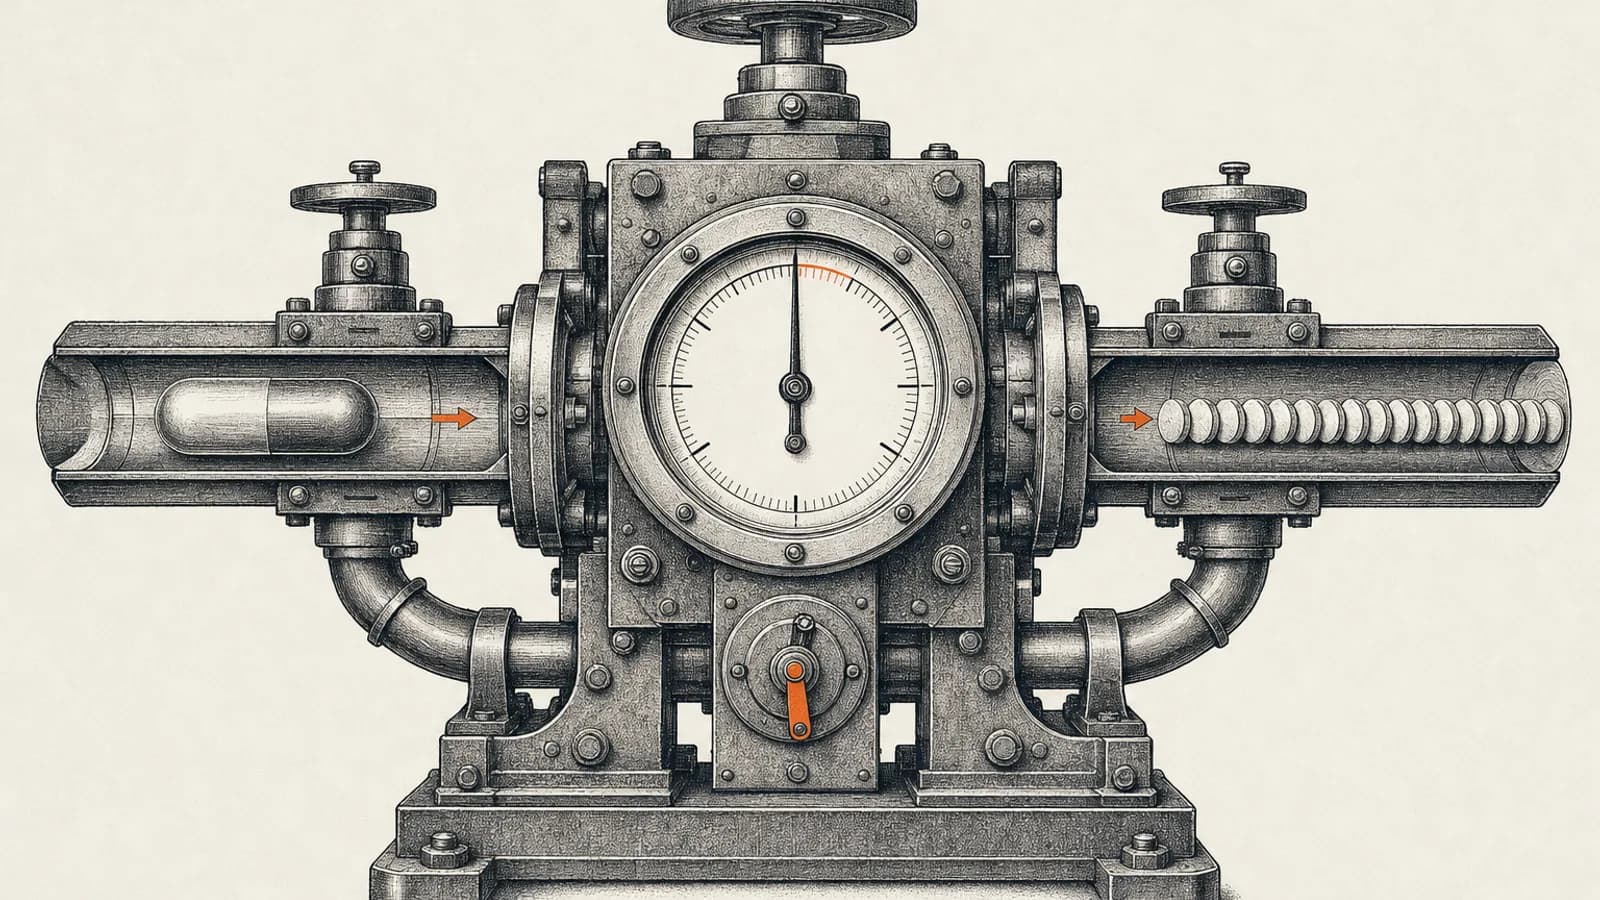
n8n charges per workflow execution. Its pricing page is unusually blunt about this: an execution is a single run of your entire workflow, and it does not matter how many steps are in the workflow or how much data it processes, it is still a single execution.
Make charges per module action. Its pricing page states that most actions consume one credit, while some advanced features that use Make's AI provider may use more. Make's help centre confirms the baseline rate for non-AI apps: one operation equals one credit.
Those two sentences are the whole comparison in miniature. On n8n the unit of cost is the run. On Make the unit of cost is the step. Zapier sits closer to Make here, billing per task for each action step, and our n8n vs Zapier comparison for startups covers that side.
Work through what that means for a real workflow. Take a document pipeline with twenty modules that runs five thousand times a month. On n8n that is five thousand executions. On Make, at one credit per module action, the same logic lands near one hundred thousand credits. The workflow is identical. The meter is not.
Now invert it. A three-step webhook relay that fires constantly is cheap on Make, because you only ever pay for three steps, and it burns a full execution every time on n8n regardless of how trivial the work is. Short and frequent favours Make. Long and deep favours n8n.
What each platform costs at the published rates
n8n's published plans are priced in euros and billed annually. Starter is twenty euros a month for 2,500 workflow executions. Pro is fifty euros a month for 10,000 executions. Business is 667 euros a month for 40,000 executions and is self-hosted only. Enterprise is custom. All plans include unlimited active workflows, which matters more than it sounds, because it removes any incentive to cram unrelated logic into one workflow.
Make's published plans are priced in US dollars. As of November 2026 the Free plan includes 1,000 credits a month. The paid Core, Pro and Teams plans are each priced by the monthly credit volume you choose, and Enterprise pricing is custom. Check Make's pricing page for the dollar figure at your volume, because it changes with the credit tier.
Resist the urge to convert currencies and declare a winner. A block of credits and a block of executions are not comparable units, and that is exactly the trap. The only honest comparison is to model your own workflows: count the average billable module actions in a typical scenario, multiply by expected monthly runs, and price that against the execution tier covering the same run count.
One detail in Make's favour, and it is a genuine one: not everything is billable. Make's pricing page states that router modules do not consume credits, and that the error handler modules Rollback, Break, Resume, Commit and Ignore count no credits. Branching and error handling are free. So the per-step meter is less punishing than a naive count suggests, and you should not model routers as cost.
The architecture consequence most teams miss
Here is the part that rarely makes it into comparison posts, and it is the one I raise first with clients.
n8n's documentation states that sub-workflow executions do not count towards your plan's monthly execution or active workflow limits. Only the parent run is counted. So you can decompose a two-hundred-node monolith into a clean parent workflow calling ten focused sub-workflows, and your bill does not change at all. Modularity, reuse, isolated testing and readable workflows are effectively free.
On a per-module meter the incentive runs the other way. Every layer of abstraction you add is another billable action. Splitting a scenario into reusable pieces has a real cost, so teams on per-step pricing tend to build fewer, longer, denser scenarios that are harder to test and harder to hand over.
Neither platform is wrong here. But you should know which behaviour your pricing model is paying you to adopt, because after eighteen months that behaviour is your codebase.
Self-hosting: what it actually buys you
This is the second genuine fork, and it is frequently misdescribed.
n8n can be self-hosted. Its documentation lists a permanently free Community edition with core features, a Registered Community edition that is free after registering your email and adds folders, debug in editor and custom execution data, plus paid Business and Enterprise editions that add SSO, environments and projects. Cloud offers Starter, Pro and Enterprise tiers, with a free trial that includes Pro features but leaves out admin roles and the public API.
Be precise about the licence, because this gets overstated constantly. n8n is not OSI open source. Its source is available under the Sustainable Use License version 1.0, which grants the right to use, copy, distribute and prepare derivative works for your own internal business purposes or for non-commercial or personal use, and permits distribution to others only free of charge for non-commercial purposes. Running n8n internally to operate your own company is squarely permitted, and so is building workflows for clients as a consultant. Hosting n8n for customers to build in, or white-labelling it, is not.
Make does not publish a self-hosted edition of the platform. Its help centre does describe an on-premise agent for Enterprise customers, but an agent that reaches into your network is a different thing from running the platform on your own hardware. If your requirement is that customer data never leaves infrastructure you control, that requirement selects n8n and the comparison ends there.
Self-hosting is not free, though, and pretending otherwise is how these projects go wrong. You are trading a licence fee for an operational burden: upgrades, backups, queue mode, monitoring, database maintenance and someone who is accountable when the instance stops at two in the morning. For teams running meaningful volume that trade is usually worth it. For a team of four automating a handful of internal handoffs, it usually is not.
The AI agent layer is priced differently again
Both platforms now ship agent capability, and this is where the two meters diverge hardest.
Make launched its new AI Agents app in early February 2026, and as of November 2026 its help centre still lists the app as open beta, with functionality and pricing explicitly subject to change. It is available on all plans using Make's own AI provider, with custom AI provider connections available on paid plans.
The credit rules are worth reading closely. Running an agent on Make's AI provider costs one credit per operation plus credits based on AI tokens consumed. On a custom AI provider connection it costs one credit per operation, and your model provider bills tokens separately. For chat, Make's AI provider costs one credit per operation plus one credit per operation from called tools plus token-based credits, while a custom provider costs one credit per operation plus one credit per called tool operation.
Read that tool clause again, because it is the sharp edge. On a per-step meter, every tool your agent decides to call is itself billable. Agent cost is therefore non-deterministic by design: the same user question can cost different amounts on different days depending on how many tools the model chooses to invoke. Budgeting for that is materially harder than budgeting for a fixed workflow.
This is also the one area where Make's 2025 move from operations to credits changed the economics. Make's help centre states that existing plans and pricing stayed the same, and that built-in AI usage is charged in credits based on the AI tokens consumed. Token-metered billing is now inside the platform meter, not just on your model provider's invoice.
On n8n, an agent that calls twelve tools inside one workflow run is still one execution. Your model provider still bills you for tokens, but the automation platform does not add a per-tool charge on top.
What changes with n8n 3.0
If you are choosing n8n in November 2026, plan for version 3.0 before you commit, not after.
n8n 3.0 entered beta on 27 October 2026, and n8n says the stable release follows in early December 2026. As of 4 November 2026 the latest stable release is 2.46.5. Once 3.0 is stable, the 2.x line gets security and critical bug fixes for 12 months. n8n also states that moving to 3.x is one way, so take a full backup and test on staging first. New builds should avoid anything on the removal list so they move across cleanly.
The published breaking changes matter for platform selection. Self-hosted n8n will require a Docker-based deployment, and npm and npx installations will no longer be supported, so if your plan was a bare npm install on a small server, revise it now. Version 1 of the AI Agent node and several older agent type modes, including SQL Agent and Conversational Agent, are being removed. The legacy Function and Function Item nodes are going, along with the Cron, Interval, HTML Extract, iCalendar and Read PDF nodes. In the Code node, the evaluateExpression method is being removed for insecure task runners, the Ask AI tab is being eliminated, and the default task timeout drops from five minutes to one minute. The paired item expression helper is also on the removal list, and Chat Hub is disabled by default with full removal planned for version 4.0.
None of this should scare you off n8n. It is ordinary platform hygiene, unusually well documented in advance. But it does mean a migration window from December 2026, and that belongs in your plan rather than your surprise budget. Our n8n 3.0 breaking changes checklist covers what to fix before upgrading.
A decision rule you can apply in an afternoon
Skip the feature matrices. Answer four questions honestly.
First, count your steps. Take your three highest-volume intended workflows and count the billable module actions in each, ignoring routers and error handlers. If the average is in low single digits, the per-step meter is not going to hurt you. If it is fifteen or more and volume is meaningful, execution pricing wins and the gap widens every month.
Second, ask whether data residency is a hard requirement or a preference. If it is genuinely hard, contractually or by regulation, that answers the question on its own.
Third, be honest about who maintains this. Self-hosting needs an owner with operational skill and time. If nobody on the team can name that person, a managed platform is the mature choice regardless of unit economics.
Fourth, look at your agent plans. If you expect agents that call many tools per interaction, model the per-tool charge explicitly, and compare it against a platform where tool calls inside one run are not separately metered.
At AbhijeetBuilts we run this exact model before recommending a platform, because the cheap answer at 5,000 runs a month is frequently the expensive answer at 50,000. In practice we deliver most production automation through our n8n development service, usually self-hosted, for the execution-based economics, the freedom to decompose workflows into maintainable parts, and the control that regulated and data-sensitive clients need. That is a default, not a dogma. For a small team automating a handful of short scenarios with no residency constraints and no appetite for infrastructure, Make is a sound choice and we will say so.
The mistake worth avoiding is treating this as a taste question. It is an arithmetic question with a maintenance question attached, and both are answerable in an afternoon with your real numbers.
If you want that afternoon done properly, with your own workflows counted, your volumes modelled against both meters, and a migration path costed before you sign anything, get in touch through the contact page on this site.
Related resources
Keep building the automation map
Move from the guide into the services and proof pages connected to this topic.
Related services
Service
Explore n8n Workflow Development
Custom n8n workflow automation for lead capture, CRM sync, AI enrichment, approvals, and notifications — built to keep running when nobody is watching.
Service
Explore AI Agent Development
AI agents for sales replies, lead memory, storyboard generation, data extraction, and structured automation outputs.
Service
Explore AI Operating System
A done-for-you AI operating system built on Claude: a second brain that knows your business, remembers everything between sessions, and safely runs your recurring work.
Further reading
Article
Read: n8n vs Zapier for Startups: Which Automation Platform Should You Choose in 2026?
A practical founder-focused comparison of n8n and Zapier, covering ease of use, flexibility, costs, AI workflows, and which platform startups should choose in 2026.
Article
Read: Google Workspace Studio vs n8n in 2026: What to Build Where
Google Workspace Studio vs n8n in 2026: what each tool actually owns, the limits that decide it, and a clear rule for which automations belong where.
Article
Read: n8n vs Activepieces in 2026: A Practical Decision Guide
n8n vs Activepieces in 2026: how licensing, billing units, self-hosting and extension models really differ, and the criteria that decide your pick.
Proof pages
Case study
See case study: Zapier to n8n Migration for a US Manufacturer: $70 a Month Down to $10
About 20 lead and attribution workflows moved from Zapier to self-hosted n8n, taking the automation bill from about $70 a month to a $10 server the client owns.
Case study
See case study: Multilingual WhatsApp Sales Bot for an International Freight Forwarder
A WhatsApp AI sales assistant that qualifies freight enquiries in three languages, remembers every conversation, and alerts the sales team the moment a quote is requested.